 Anvil Tools
Test environment
Chrome 154.0.8037.97 and Edge 154.0.4258.53; 1100 × 850 viewport.
Fixture and expected result
Counts follow the documented whitespace and JavaScript UTF-16 rules, even where those rules differ from grapheme clusters or linguistic words.
Reproduction steps
- Download the text fixture and recorded cases.
- Paste one line at a time into Word Counter.
- Compare words, characters, characters without spaces, sentences, and paragraphs.
- Use the receiving platform’s rule when a submission has a strict limit.
Observed result
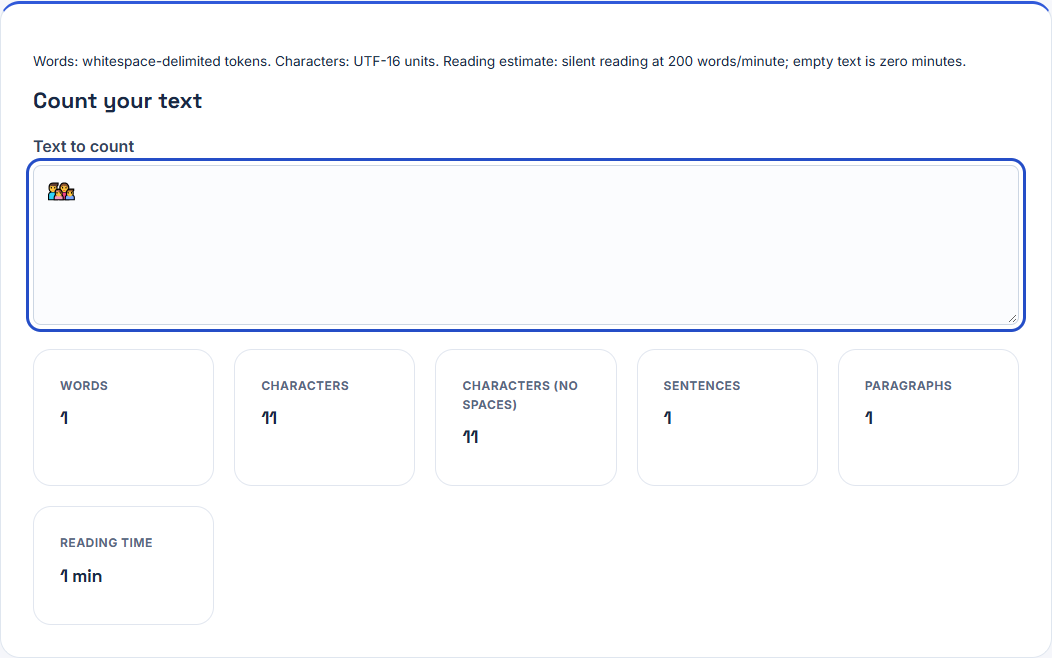
Both browser runs matched all 12 fixed cases. A family emoji was one whitespace-delimited word and 11 UTF-16 code units; café used four units while the visually similar combining form used five.
Downloadable evidence
The fixture library publishes SHA-256 hashes for exact-byte verification.
What this test does not establish
This is not language-aware tokenization or grapheme-cluster counting. RTL display, screen-reader pronunciation, and platform-specific limits need separate testing.
Related tool and guide
Word & Character Counter · How Long Should a Voiceover Script Be?
Change history
- : Structured data, image dimensions, and fixture links reviewed.
- : Report organized under Anvil Tools Lab; evidence and limitations reviewed.